Cursor Pagination: Stop Repeating Rows in a Changing Feed
Build stable cursor pagination with a runnable JavaScript example, timestamp tie-breakers, PostgreSQL queries, and a practical API checklist.
Quick answer
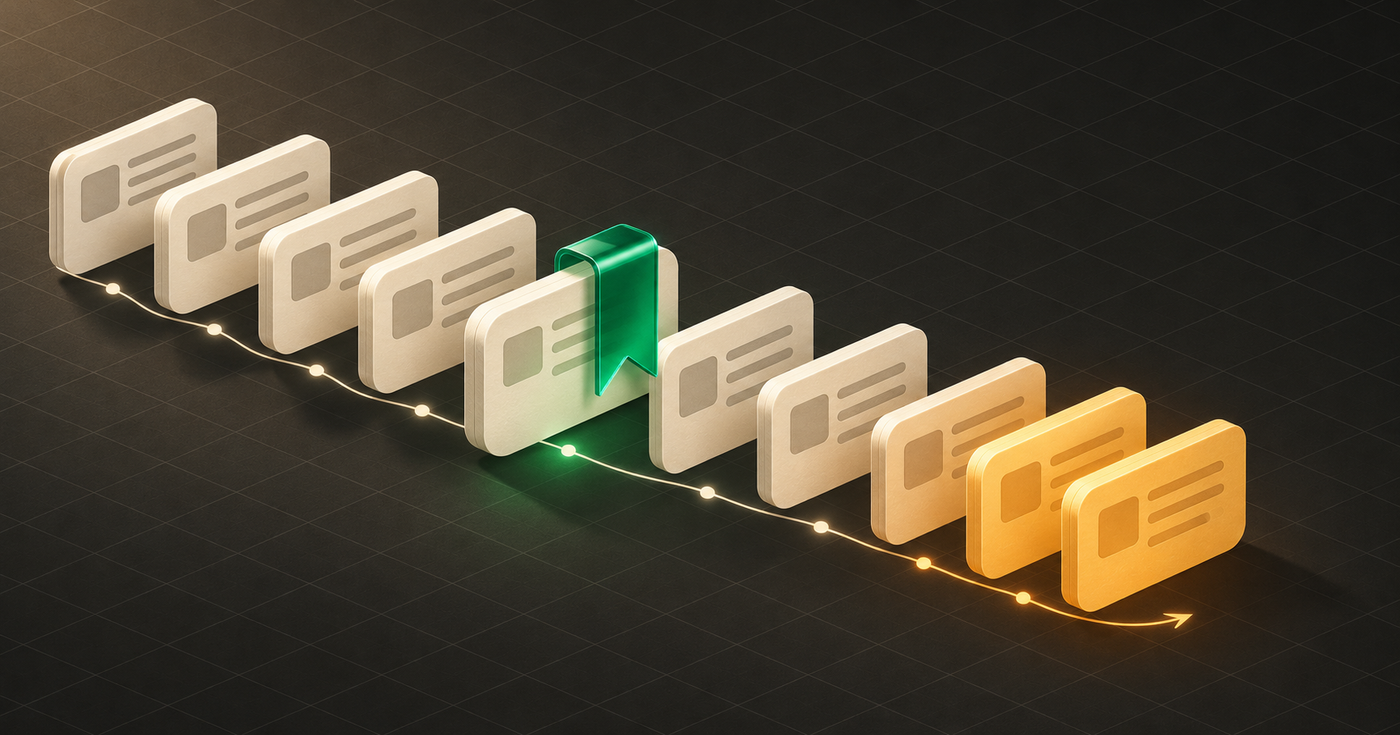
For a changing feed, continue from the last returned record's ordered keys rather than skipping a number of rows. Use a deterministic order such as creation time descending, then unique ID descending. Put both values in the cursor, use a strict comparison for the next page, and fetch one extra row to determine whether another page exists. A cursor stabilizes the boundary; it does not freeze the dataset.
Imagine an operations dashboard listing recent orders. Page one shows orders 105 and 104. Before the operator presses Next, order 106 arrives. An offset of two now skips 106 and 105, so page two starts with 104 again. The database followed the request exactly; the position changed between requests.
Define the order before defining the cursor
Creation timestamps are often shared by several records. Ordering only by created_at leaves those ties unresolved. Add a unique, non-null ID as a tie-breaker and use the same ordering everywhere: the query, the cursor comparison, and any client-side fixture. PostgreSQL's LIMIT and OFFSET documentation explains why limited queries need a unique order and why skipping large offsets can be expensive.
For newest-first results, the next record must have an earlier timestamp, or the same timestamp and a smaller ID. Using only an earlier timestamp would skip records tied with the boundary. Using a less-than-or-equal comparison would include the boundary again. Those are separate bugs from the shifting offset.
Run the failure and the fix
Save this as pagination-lab.mjs and run node pagination-lab.mjs with a supported Node.js installation. It uses only a built-in assertion module, makes no network requests, and simulates a newest-first order feed. The function is an executable model of the selection rule, not a database adapter or a performance benchmark.
import assert from 'node:assert/strict';

// Fixture timestamps are integer milliseconds, IDs are safe integers.
// Production cursors must preserve the database's exact key precision.
const records = [
  { id: 105, createdAt: 3000 },
  { id: 104, createdAt: 2000 },
  { id: 103, createdAt: 2000 },
  { id: 102, createdAt: 1000 },
  { id: 101, createdAt: 1000 },
];
const newestFirst = (rows) => [...rows].sort(
  (a, b) => b.createdAt - a.createdAt || b.id - a.id,
);
const ids = (rows) => rows.map((row) => row.id);

function pageAfter(rows, after = null, size = 2) {
  if (!Number.isInteger(size) || size < 1 || size > 100) {
    throw new RangeError('Page size must be an integer from 1 to 100');
  }
  if (after !== null && (
    typeof after !== 'object' ||
    !Number.isSafeInteger(after.createdAt) ||
    !Number.isSafeInteger(after.id)
  )) throw new TypeError('Invalid cursor keys');

  const candidates = newestFirst(rows).filter((row) =>
    after === null || row.createdAt < after.createdAt ||
    (row.createdAt === after.createdAt && row.id < after.id),
  ).slice(0, size + 1);
  const items = candidates.slice(0, size);
  const hasNextPage = candidates.length > size;
  const last = items.at(-1);
  return {
    items,
    hasNextPage,
    // Cursor is the last RETURNED row, never the extra look-ahead row.
    nextCursor: hasNextPage ? { createdAt: last.createdAt, id: last.id } : null,
  };
}

const first = pageAfter(records);
assert.deepEqual(ids(first.items), [105, 104]);
const changed = [{ id: 106, createdAt: 4000 }, ...records];
const offsetSecond = newestFirst(changed).slice(2, 4);
const second = pageAfter(changed, first.nextCursor);
assert.deepEqual(ids(offsetSecond), [104, 103]); // Repeats 104.
assert.deepEqual(ids(second.items), [103, 102]); // Includes tied timestamp.
assert.equal(second.hasNextPage, true);
const third = pageAfter(changed, second.nextCursor);
assert.deepEqual(ids(third.items), [101]);
assert.equal(third.nextCursor, null);
assert.equal(third.hasNextPage, false);

// A value-based cursor still works if the boundary record was deleted.
assert.deepEqual(ids(pageAfter(
  changed.filter((row) => row.id !== 104), first.nextCursor,
).items), [103, 102]);
assert.deepEqual(pageAfter([]), { items: [], hasNextPage: false, nextCursor: null });
assert.equal(pageAfter(records.slice(0, 2)).hasNextPage, false);
assert.throws(() => pageAfter(records, null, 0), RangeError);
assert.throws(() => pageAfter(records, { createdAt: '2000', id: 104 }), TypeError);

// Walk every fixture row with a one-item page and tied timestamps.
const visited = [];
let cursor = null;
do {
  const page = pageAfter(records, cursor, 1);
  visited.push(...ids(page.items));
  cursor = page.nextCursor;
} while (cursor !== null);
assert.deepEqual(visited, [105, 104, 103, 102, 101]);
console.log('Offset page 2:', ids(offsetSecond).join(', '));
console.log('Cursor page 2:', ids(second.items).join(', '));
console.log('All pagination checks passed.');
The output is Offset page 2: 104, 103, then Cursor page 2: 103, 102, then All pagination checks passed. The cursor keeps 103 even though it shares a timestamp with 104. The extra candidate determines hasNextPage, while the cursor points to the last item actually returned. Using the extra candidate as the boundary would skip that candidate on the following request.
The deletion assertion matters: this implementation stores boundary values and does not need to look up the original record. Deleting order 104 therefore does not invalidate the comparison. The single-item traversal assertion makes timestamp ties cross page boundaries repeatedly, which catches mistakes that a large first page can hide.
Translate the boundary into a database query
For a PostgreSQL orders table with non-null tenant_id, created_at, and a unique non-null id, the following JavaScript strings illustrate parameterized SQL. Bind the tenant from the authenticated request context. Bind the timestamp and ID from a validated cursor, and request pageSize plus one rows. Use the first query when no cursor is supplied.
const firstPageSql = `
  SELECT id, created_at
  FROM orders
  WHERE tenant_id = $1
  ORDER BY created_at DESC, id DESC
  LIMIT $2
`;
// Parameters: [authenticatedTenantId, pageSize + 1]

const nextPageSql = `
  SELECT id, created_at
  FROM orders
  WHERE tenant_id = $1
    AND (created_at, id) < ($2::timestamptz, $3::bigint)
  ORDER BY created_at DESC, id DESC
  LIMIT $4
`;
// Parameters: [authenticatedTenantId, cursor.createdAt,
//              cursor.id, pageSize + 1]
The tuple comparison follows the same left-to-right ordering as the fixture. PostgreSQL documents this in row constructor comparisons. Both directions here are descending, so a strict less-than tuple comparison fits. Mixed ascending and descending keys require a deliberately matched predicate; do not change ORDER BY and leave the boundary unchanged. Null keys also require an explicit policy, which is why this example excludes them.
A candidate index for this access pattern is CREATE INDEX orders_feed_idx ON orders (tenant_id, created_at DESC, id DESC). Check the actual query plan with representative data and filters before claiming a speed improvement. PostgreSQL's multicolumn index documentation describes how leading equality constraints affect index scans. An index is a workload choice, not proof of a particular response time. The runnable JavaScript assertions validate selection behavior; these SQL templates still need integration tests against your schema and database.
Preserve the exact key values
The fixture uses safe integer IDs and integer millisecond timestamps to keep the comparison visible. Production database values may need more precision. If a database timestamp has fractional digits your JavaScript Date conversion discards, round-tripping it through Date can move the boundary. Preserve the full database timestamp representation in the cursor, and bind it back to the correct database type.
Likewise, carry large integer IDs as decimal strings when crossing JSON boundaries. Turning an out-of-range ID into a JavaScript Number can change the value before the next query runs. The large JSON ID guide has a separate executable example of that failure. Do not replace numeric ordering with arbitrary string ordering in an in-memory implementation: decimal strings such as 9 and 10 sort differently lexicographically.
Give the cursor an API contract
The lab accepts a small object so the boundary is easy to inspect. A public endpoint can encode that object as an opaque token, but encoding does not make it trusted. Validate token length, version, field types, supported sort order, page size, and the filter context before issuing a query. Reject malformed cursors clearly rather than silently restarting at page one.
Keep tenant authorization in every query, independently of the cursor. Bind the token to the query's filters and sort mode, or reject a token when those settings change. If clients must not alter the boundary or embedded context, use an authenticated token design with appropriate key handling. Never interpolate cursor values into SQL text. The site's SQL formatter can make a query easier to inspect; formatting is not parameterization or authorization.
A cursor is not a frozen export
Our test inserts a newer record ahead of the boundary. A live feed can show that new order on refresh while allowing the current traversal to continue through older records. An insertion behind the boundary can still appear on a later page. A deleted record may disappear. If an existing record's sort key changes across the boundary, it can be missed or returned again. Prefer immutable ordering keys when the product requires stable traversal.
For an export that must represent one consistent dataset, define a snapshot or materialization strategy separately. PostgreSQL's transaction isolation documentation distinguishes statement snapshots at Read Committed from the stable snapshot used within a Repeatable Read transaction. Separate HTTP requests do not automatically share a transaction snapshot. Holding a transaction open throughout a human browsing session is also an operational decision, not a default pagination technique.
Offsets remain useful for small, sufficiently stable lists and interfaces requiring arbitrary page numbers. Cursors naturally express next-page traversal, so the UI may need Next and Previous controls instead of a jump to page 500. Choose the behavior the reader or operator needs, then make its consistency limits explicit.
A pagination checklist before shipping
- Make the sort deterministic with a unique tie-breaker and a clear null policy.
- Match every cursor key and comparison direction to the query's ORDER BY.
- Preserve timestamp precision and large IDs across serialization.
- Fetch page size plus one, and advance from the last returned item.
- Test insertions, boundary deletion, tied keys, empty results, and exact-size final pages.
- Keep authorization and filters consistent on every request; validate cursor context.
- Measure the actual query plan and index behavior on realistic data.
- Document whether the endpoint offers a live traversal or a consistent snapshot.
A useful pagination test changes the data between requests. If the only fixture is a static list with unique timestamps, both offset and cursor implementations can look correct while the real dashboard repeats an order the next morning.
Related Posts
Fetch Timeouts: Cancel Slow Requests and Response Bodies
Use AbortSignal to bound fetch and body reads, preserve caller cancellation, and test timeout behavior with a working local HTTP server.
Promise.all Is Not a Concurrency Limit: Bound API Fan-Out
Limit API fan-out with a tested JavaScript worker pool that preserves result order, records failures, and bounds active tasks.
Large JSON IDs: Stop JavaScript From Rounding Database Keys
Keep large database IDs exact across JSON APIs with string contracts, boundary validation, and runnable JavaScript precision tests.