UUIDs: Pick Identifiers That Survive Real Systems
Use UUIDs deliberately: choose the right identifier shape, keep IDs opaque, avoid collisions, and test how values move through APIs and databases.
Quick answer
Choose a UUID version for the identifier’s job, preserve its value across API and database boundaries, and test indexing and ordering separately. An identifier is not an authorization check, and a UUID alone does not make a resource safe to expose.
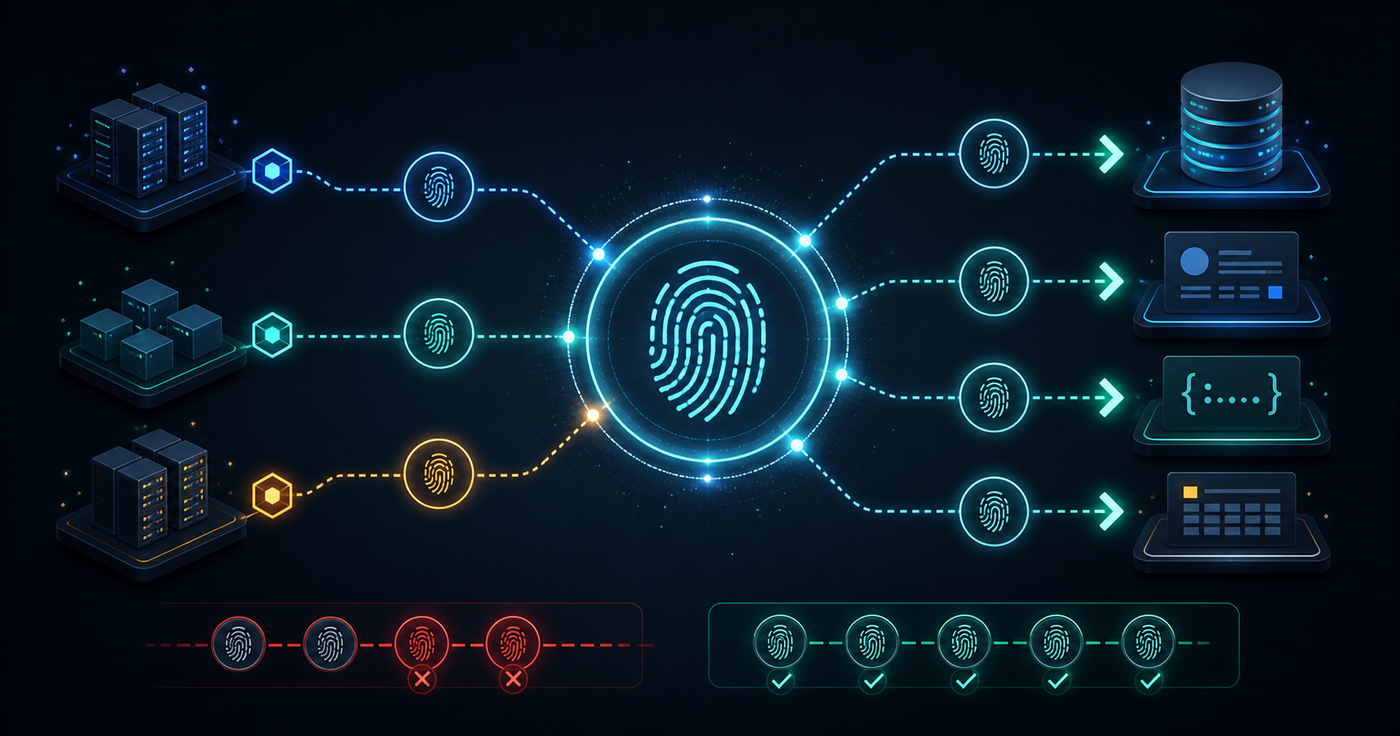
UUIDs are convenient because they let systems create identifiers without asking one central database for the next number. That makes them useful in distributed jobs, offline clients, imports, queues, and public APIs.
They are not magic. A UUID still has to fit the database, URLs, logs, indexes, and user-facing workflows around it.
Name the Identifier Boundary
Before generating IDs, decide where the identifier is allowed to travel. Internal database IDs, public resource IDs, idempotency keys, trace IDs, and import row IDs do not all need the same behavior.
- Use opaque IDs when clients should not infer order or count.
- Keep display labels separate from permanent identifiers.
- Avoid using names, emails, or slugs as stable primary IDs.
- Do not expose sequential IDs when enumeration would create risk.
- Log IDs consistently so support and debugging can follow one object across services.
Keep IDs as Strings Across Boundaries
UUIDs should move through APIs as strings. Do not coerce them into numbers, trim them for storage, or change their case in one service and not another. Small formatting changes can make an ID impossible to match later.
type Resource = {
  id: string
  createdAt: string
  status: 'pending' | 'ready'
}
A string type also makes validation more explicit. Your API can reject malformed values at the edge instead of letting bad IDs leak into queries and dashboards.
Watch Index and Sorting Behavior
Random IDs distribute writes well, but they may not sort in creation order. If product or operations teams need chronological lists, store a separate timestamp and sort by that timestamp instead of assuming ID order has meaning.
For large tables, check the index and storage behavior in the database you actually use. Identifier choice is part application design and part data modeling.
The UUID Checklist
- Decide whether the ID is internal, public, temporary, or permanent.
- Keep generated IDs opaque to clients.
- Pass UUIDs as strings through JSON, forms, URLs, and logs.
- Validate IDs at API boundaries before querying.
- Use separate timestamps for sorting and reporting.
- Avoid truncating IDs for anything that must be unique.
- Store human-readable names separately from stable identifiers.
Use a UUID Generator Before Wiring IDs
Use the UUID Generator at /tools/uuid-generator/ when you need sample IDs for fixtures, tests, API examples, or manual setup. It is useful for checking how IDs look in URLs, tables, logs, and forms before the real workflow exists.
Good ID design is boring in the best way. The value is unique, opaque, validated, and stored consistently enough that nobody has to think about it during an incident.
Sources and further reading
These references explain the standards and APIs discussed in this guide. Check the documentation for the versions and services in your environment.
Related Posts
Fetch Timeouts: Cancel Slow Requests and Response Bodies
Use AbortSignal to bound fetch and body reads, preserve caller cancellation, and test timeout behavior with a working local HTTP server.
Cursor Pagination: Stop Repeating Rows in a Changing Feed
Build stable cursor pagination with a runnable JavaScript example, timestamp tie-breakers, PostgreSQL queries, and a practical API checklist.
Promise.all Is Not a Concurrency Limit: Bound API Fan-Out
Limit API fan-out with a tested JavaScript worker pool that preserves result order, records failures, and bounds active tasks.